How to Read Experiment Results
Read and interpret Statsig experiment results, including scorecards, primary metrics, lift, confidence intervals, and statistical significance indicators.
The Results tab shows how each experiment group performed on your primary and secondary metrics: the relative lift, its confidence interval, and whether the result is statistically significant. Use it to check exposures and the Scorecard for a running or completed experiment. To filter or group results by a dimension the Scorecard doesn't show, use a custom Explore query.
Cumulative exposures
| Date | GPT-3 (Control) | GPT-4 | GPT-4o |
|---|---|---|---|
| Feb 17, 2026 | 0 | 0 | 0 |
| Feb 18, 2026 | 6,526 | 7,338 | 7,029 |
| Feb 19, 2026 | 12,757 | 13,667 | 13,364 |
| Feb 20, 2026 | 19,214 | 19,710 | 19,406 |
| Feb 21, 2026 | 23,169 | 23,425 | 23,402 |
| Feb 22, 2026 | 23,412 | 23,691 | 23,683 |
| Feb 23, 2026 | 23,884 | 24,233 | 24,185 |
| Feb 24, 2026 | 24,385 | 24,732 | 24,702 |
| Feb 25, 2026 | 24,781 | 25,159 | 25,154 |
| Feb 26, 2026 | 25,198 | 25,579 | 25,575 |
| Feb 27, 2026 | 25,559 | 25,976 | 26,013 |
| Feb 28, 2026 | 25,851 | 26,227 | 26,296 |
| Mar 1, 2026 | 26,099 | 26,501 | 26,562 |
| Mar 2, 2026 | 26,659 | 26,974 | 27,093 |
| Mar 3, 2026 | 27,069 | 27,438 | 27,546 |
| Mar 4, 2026 | 27,474 | 27,863 | 27,965 |
| Mar 5, 2026 | 27,949 | 28,288 | 28,375 |
| Mar 6, 2026 | 28,376 | 28,649 | 28,789 |
| Mar 7, 2026 | 28,630 | 28,919 | 29,091 |
| Mar 8, 2026 | 28,892 | 29,155 | 29,326 |
| Mar 9, 2026 | 29,364 | 29,713 | 29,906 |
| Mar 10, 2026 | 29,844 | 30,178 | 30,418 |
| Mar 11, 2026 | 30,331 | 30,583 | 30,870 |
| Mar 12, 2026 | 30,715 | 31,015 | 31,273 |
| Mar 13, 2026 | 31,131 | 31,470 | 31,712 |
| Mar 14, 2026 | 31,432 | 31,763 | 32,000 |
| Mar 15, 2026 | 31,668 | 32,028 | 32,261 |
| Mar 16, 2026 | 32,130 | 32,586 | 32,728 |
| Mar 17, 2026 | 32,624 | 33,091 | 33,238 |
| Mar 18, 2026 | 33,085 | 33,575 | 33,634 |
| Mar 19, 2026 | 33,462 | 33,991 | 34,018 |
| Mar 20, 2026 | 33,905 | 34,439 | 34,405 |
| Mar 21, 2026 | 34,163 | 34,685 | 34,682 |
| Mar 22, 2026 | 34,433 | 34,937 | 34,943 |
| Mar 23, 2026 | 34,986 | 35,493 | 35,460 |
| Mar 24, 2026 | 35,476 | 35,982 | 35,960 |
| Mar 25, 2026 | 35,952 | 36,395 | 36,404 |
| Mar 26, 2026 | 36,421 | 36,790 | 36,814 |
| Mar 27, 2026 | 36,855 | 37,240 | 37,195 |
| Mar 28, 2026 | 37,118 | 37,528 | 37,452 |
| Mar 29, 2026 | 37,380 | 37,814 | 37,723 |
| Mar 30, 2026 | 37,845 | 38,318 | 38,286 |
| Mar 31, 2026 | 38,316 | 38,812 | 38,727 |
| Apr 1, 2026 | 38,776 | 39,205 | 39,166 |
| Apr 2, 2026 | 39,176 | 39,610 | 39,570 |
The Cumulative Exposures chart shows exposures: the unique experimental units enrolled in the experiment, typically unique users, or devices for device-level experiments. The timeline shows when the experiment started and how many exposures Statsig enrolled each day. Use this chart to verify the rate at which users entered each group, the total number exposed, and whether the target ratio matches what you configured in experiment setup. Click the See More option to expand the chart.
Scorecard
The experiment Scorecard shows the metric lifts for all of the primary and secondary metrics that you set up when creating the experiment.
Real-time results in the first 24 hours
Statsig calculates the Scorecard results hourly up to the first 24 hours after you start your experiment. Statsig calculates Scorecard results before the first daily metric results run. This hourly calculation applies only to Statsig Cloud. For Warehouse Native projects, reload results on demand or set up a daily schedule. Use the real-time Scorecard to confirm that Statsig calculates exposures and metrics as expected, and to debug your experiment or gate setup.
Don't make any experiment decisions based on real-time results data in this first 24-hour time period. Let the experiment reaches its target duration, which is when your primary metrics reach experimental power, before you make any decisions. For more information about target duration, go to Target Duration.
Until the first daily run, the real-time view differs from daily results in the following ways:
- Metric lifts don't have confidence intervals.
- There's no time-series view of metric trends.
- There's no projected topline impact analysis.
- You can't apply advanced statistical treatments such as CUPED or sequential testing.
Daily Scorecard results
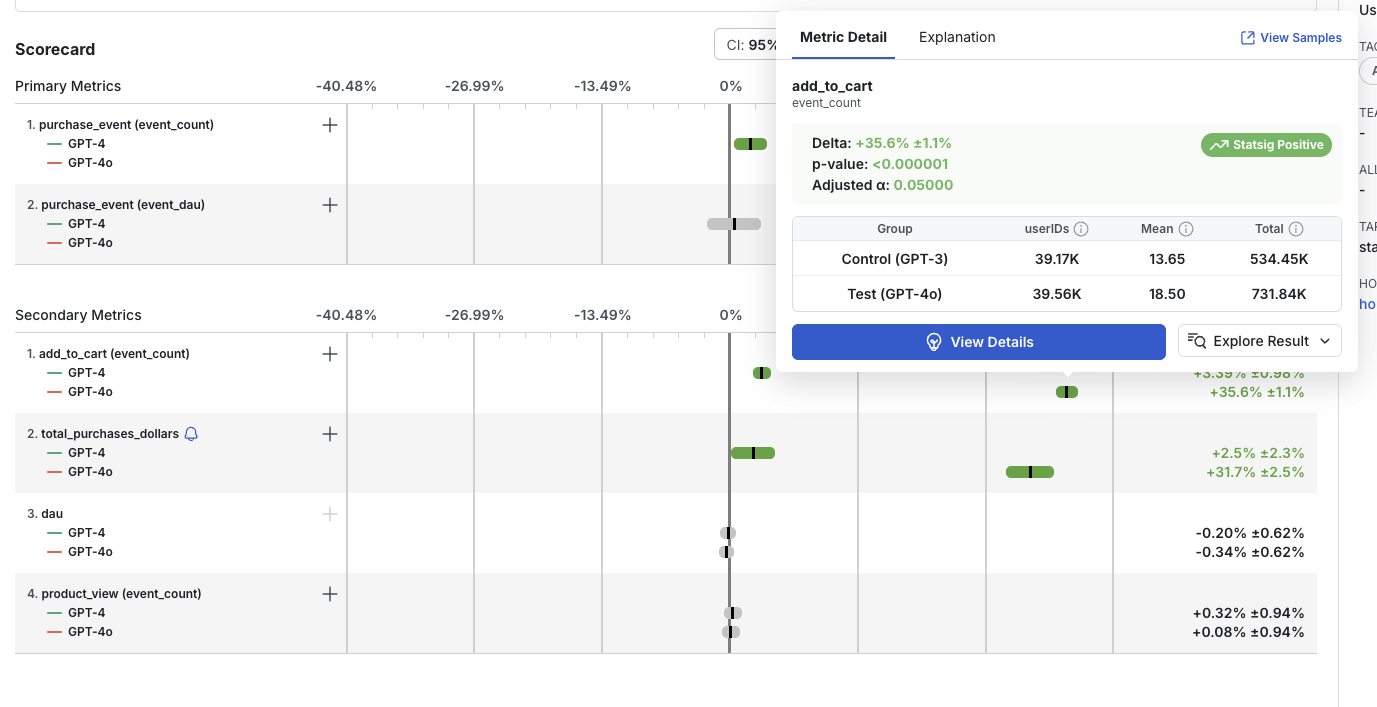
The daily results run calculates the difference between randomization groups (for example, test and control) across your metric suite and applies a statistical test to the results. Refer to Statsig's stats engine for details.
For every metric, Statsig shows you:
- The calculated relative difference (Delta %).
- The confidence interval.
- Whether the result is statistically significant. Positive lifts are green, negative lifts are red, and non-significant results are grey.
The formula for calculating lift is:
Statsig reports confidence intervals at the selected significance level (95% by default). In a typical two-sided Z-test, Statsig shows the confidence interval as standard error.
Statsig automatically applies 99.9% winsorization to event_count, event_count_custom, and sum metrics. Winsorization caps extreme outlier values to reduce their impact on experiment results. For metrics in the Scorecard or Monitoring Metrics sections of your experiment or gate, you can also apply optional statistical treatments such as: CUPED (pre-experiment bias reduction) and sequential-testing-adjusted confidence intervals.
90-day compute window
By default, Statsig computes experiment results for only the first 90 days of your experiment. Statsig notifies you by email as you approach the 90-day cap. At that point, you can extend the compute window by 30 days at a time. If the experiment runs beyond the compute window, Statsig stops adding new users to the experiment's results. Analysis for users already exposed continues until you make a decision on the experiment.
This calculation window only affects whether Statsig includes a user in the experiment's analysis. It doesn't affect the experience each user receives: new users still receive the experience for the group Statsig randomizes them into.
Experiment results views
On the Results tab, select Display Options and then set Chart Type to choose how the Scorecard renders metric lifts.
| Chart Type | What it shows |
|---|---|
| Cumulative (default) | The aggregate difference between experiment groups, with the corresponding confidence intervals. Hover over a metric for the raw statistics behind the lift calculation and the topline impact. |
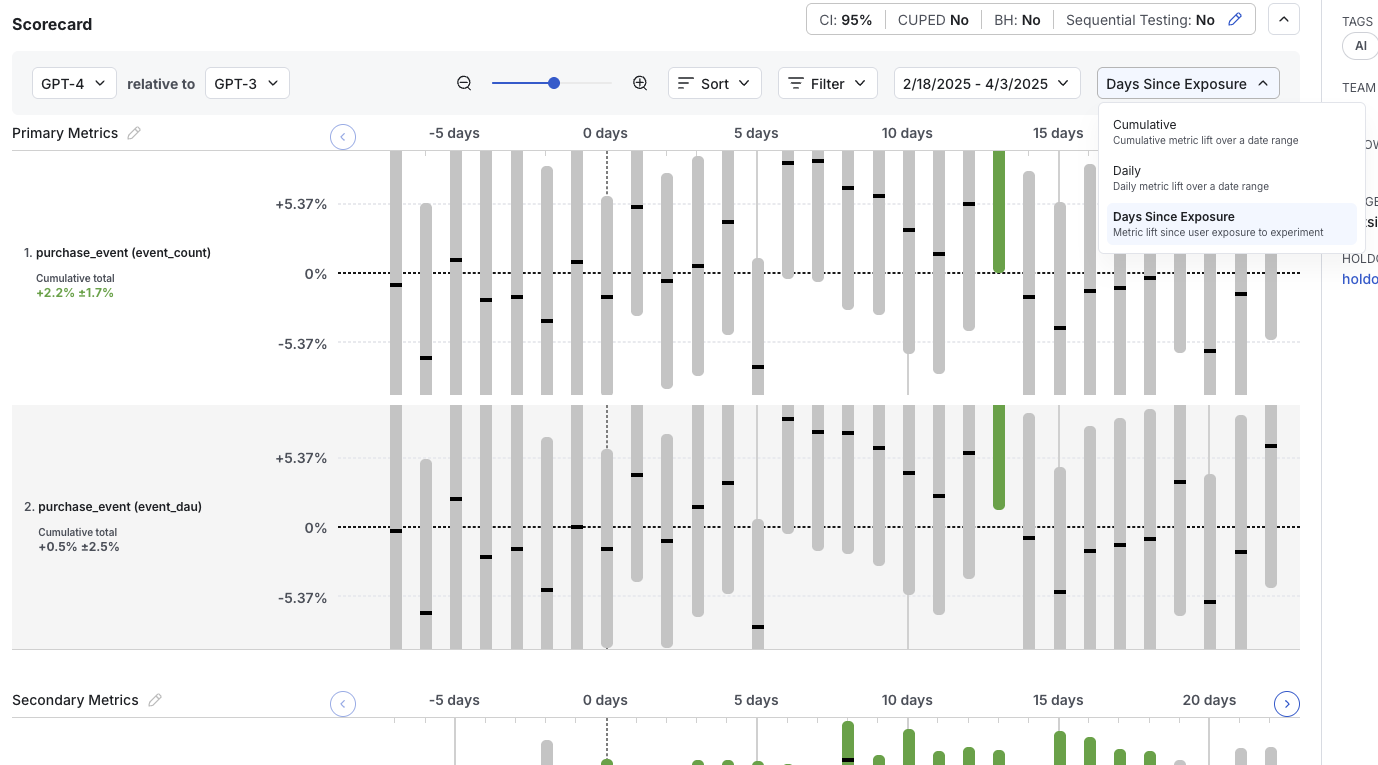
| Daily | The difference between experiment groups, aggregated by days since the experiment started. |
| Days Since Exposure | The difference between experiment groups, aggregated by days since each user's exposure to the experiment. |
| Table | The same data as the cumulative view, in a table with additional fields. |
The Display Options panel also includes:
- Data: Choose the value to display: Relative Delta, Absolute Delta (per unit), Relative or Absolute Topline Impact, or Relative or Absolute Projected Launch Impact. For what the impact values mean, go to Topline impact.
- Zoom: Adjust the zoom level of the chart.
- Sort By / Organize By: Control the order and grouping of the metrics.
- Filters: Filter the displayed metrics by tag or filter group.
Dimensions
You can break down a Scorecard metric by a user dimension or by an event dimension.
User dimensions
User dimensions are user-level attributes that are either part of the user object you log or additional metadata that Statsig extracts. Examples include operating system, country, and region.
To filter or group by user dimensions, create a custom Explore query on the Explore tab. For example, view results for users in the US, or for users on iOS grouped by country.
Event dimensions
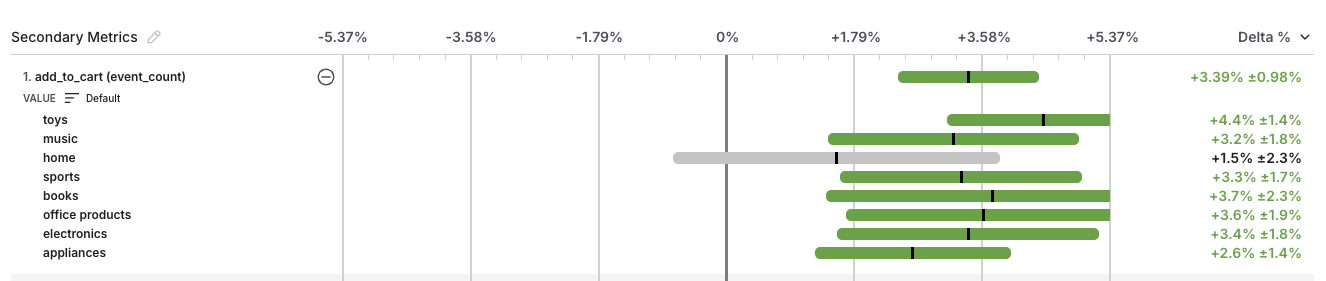
Event dimensions are the value or metadata logged as part of the custom event that defines the metric. To break a metric down by categories specific to that metric, specify the dimension in the value or metadata attribute when you log the source event. For example, when you log a "click" event, you can also log the target category in the value attribute. Statsig automatically generates results for each category in addition to the top-level metric.
To view breakdowns for all categories within a metric, select the (+) sign next to the metric.
Significance level settings
Open the Comparison & Stats panel to view Scorecard results at different significance levels and adjust the statistical settings. To open it, select the pencil icon next to the Test and Control summary row on the Scorecard. The panel also includes Compare and relative-to group pickers that control which groups Statsig compares.
- Confidence Interval: Changes the confidence interval displayed with the metric deltas. Choose from 80%, 90%, 95%, 98%, or 99%. A lower confidence interval accepts a higher false-positive rate in exchange for faster, directional results.
- CUPED: Toggle CUPED on or off. This setting applies only to Scorecard metrics; Statsig doesn't apply CUPED to non-Scorecard metrics.
- Sequential Testing: Applies a correction to p-values and confidence intervals to reduce the increased false positive rate caused by evaluating results before the target completion date. This setting appears only for experiments with a set target duration.
- SPRT: Toggle the Sequential Probability Ratio Test (SPRT) on or off. SPRT is a sequential testing methodology that supports unlimited peeking without alpha-spending or confidence-interval penalties. Refer to Sequential Probability Ratio Tests for details, including its configuration options.
- Power Parameter: Appears when SPRT is on. Sets the target statistical power (1 − β) that Statsig uses to compute the SPRT decision boundaries. The default is 80%; choose from 80%, 90%, 95%, 98%, or 99%. This isn't the per-metric effect size: set the Minimum Detectable Effect (MDE) and Cohen's d separately during experiment setup, as described in Power analysis and setting Cohen's d.
Multiple-hypothesis corrections aren't in this panel. Set Bonferroni correction and the Benjamini-Hochberg procedure in Advanced Settings on the experiment's Setup tab.
Restarting results
If your experiment has stopped computing results, select Restart to resume updates. Understand how Restart behaves before you proceed:
- A Restart isn't a Reset of your experiment. A Restart doesn't re-salt (re-randomize) units, and all users continue to receive the same group assignments.
- Statsig begins computing experiment results from the restart point, so your metric results start over. Old results may still appear in time series and Explore query views, but Statsig doesn't carry them forward or update them.
- Your Cumulative Exposures chart updates based on new exposures. The duration of the pause in computations determines whether the chart starts over from zero or includes past exposures.
To avoid needing a Restart, extend experiments while they're running. Watch for email alerts from Statsig and check your experiments regularly.
Was this helpful?
For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.