For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.
Create an Experiment
Learn how to create and configure a new experiment in the Statsig console, including scorecard setup and allocation targeting.
Create an experiment in the Statsig console when you want to compare two or more variants of a feature against your key metrics. If you only need to roll out a single change safely, without measuring variant lift, create a feature gate instead. Before Statsig can create an experiment, it needs a name, a hypothesis, at least one target application, and a scorecard with at least one primary metric.
For an end-to-end guide that includes integrating the Statsig SDK, go to Run your first experiment.
Experiments behave differently in Warehouse Native. Read about Configuring Experiments in Warehouse Native.
User-level experiments
To create a user-level experiment:
- In the Statsig console, navigate to Experiments in the left-hand navigation panel.
- Click Create.
- Enter a name for your experiment.
- Add the hypothesis you're trying to prove.
- The Create button stays disabled until you select a targeting option. In the Targeting section, select at least one Target Application.
- To add this experiment to an existing layer, select Advanced, then click Add Layer. To create a new layer, select Create New Layer. By default, your experiment runs in its own layer. A layer manages multiple experiments and feature gates together.
- Add any other details you want, then click Create.
The experiment creation modal includes several additional controls:
- Experiment Type: The default is Standard A/B/n. Statsig also supports other types, such as Switchback Tests and A/A tests.
- Template: Pre-fill the experiment's configuration from a saved template. Go to Templates for more details.
- Team: Assign the experiment to an internal team.
- Tags: Add tags to organize and filter your experiments.
Configure your scorecard
A scorecard documents your hypothesis and the primary and secondary metrics that measure it. You must enter a hypothesis and select at least one primary metric before you can create the experiment. Statsig computes scorecard metrics daily, and they're eligible for advanced treatments such as CUPED and Sequential Testing.
- Hypothesis: A rich-text field. Use its toolbar to apply headings, bold, italic, underline, strikethrough, links, text color, highlighting, bulleted and numbered lists, blockquotes, images, and code blocks.
- Primary Metrics: The metrics you expect the experiment to directly affect.
- Secondary Metrics: Metrics you monitor for unintended side effects. They aren't the primary focus of the experiment.
The Hypothesis field includes a template that you can modify:
We believe that [change or feature] for [user segment] will [desired outcome] because [reason or insight]. We will measure success using [primary metric], and monitor [guardrail metrics] to ensure no negative impact.
For best practices on configuring your scorecard, go to Read Results.
Configure allocation and targeting
Allocation sets how many users you include in the experiment. Targeting sets which users you include.
Allocation
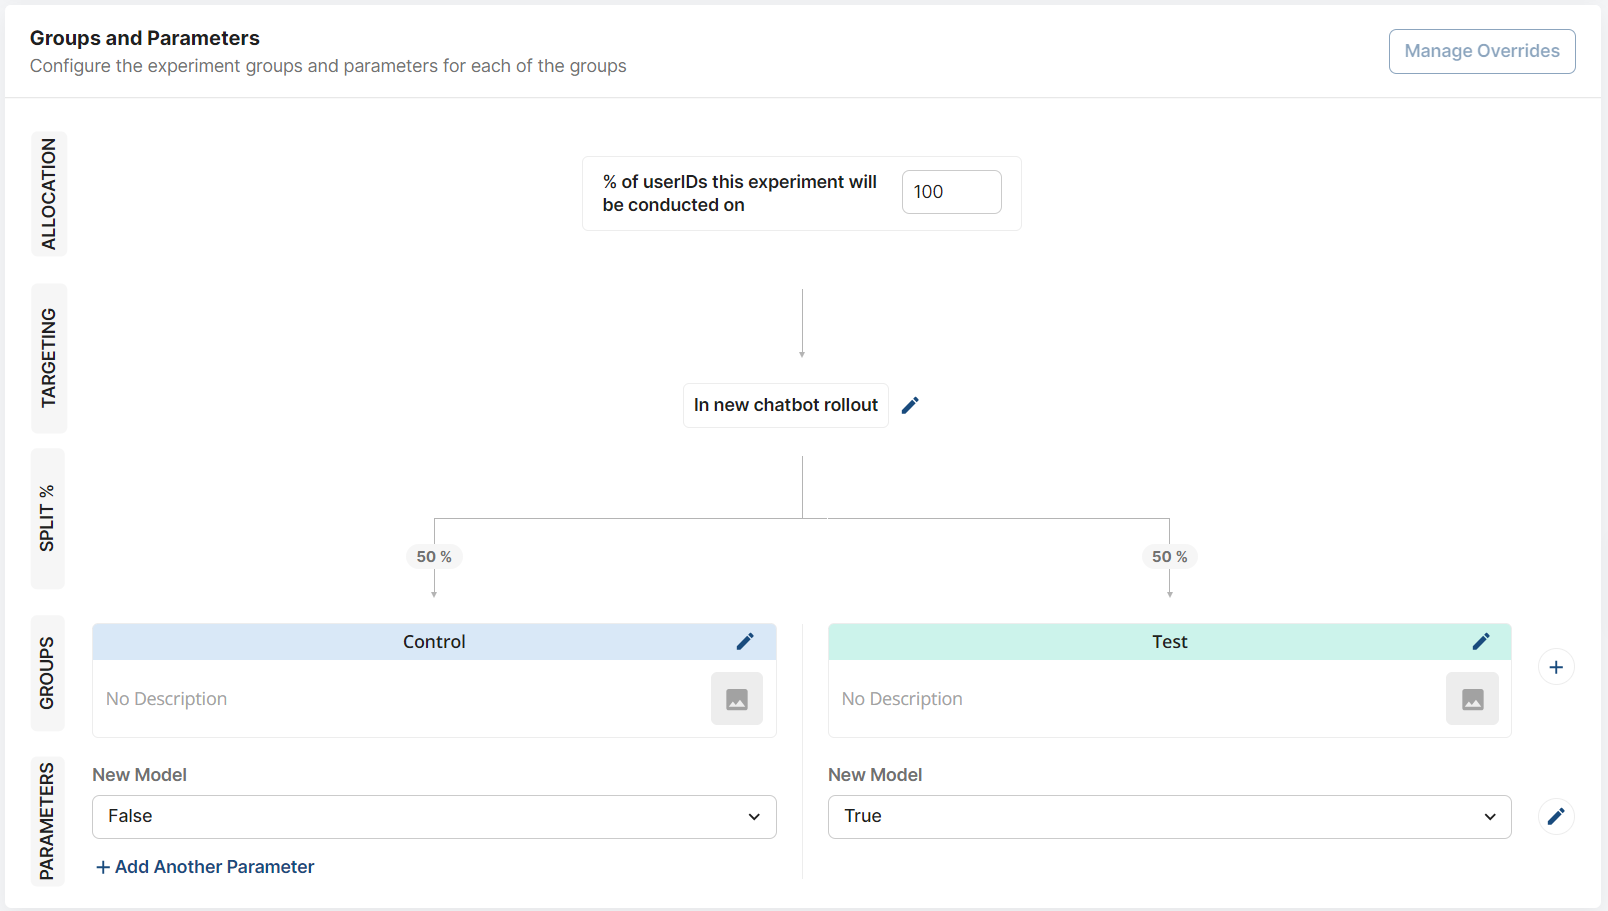
Allocation is the percentage of eligible users that Statsig assigns to your experiment, up to 100%. Start with a smaller percentage, verify that the experiment is stable, then increase the allocation.
You can change the allocation from 0% to 100% at any time after the experiment starts. Decreasing allocation biases group allocation and pollutes your metric results, so don't decrease allocation without resetting the experiment.
Targeting
Targeting limits the experiment to the users who meet the conditions you define. To configure targeting, edit the Targeting section. You can set new targeting criteria or reference an existing feature gate.
- For basic targeting criteria, create them with inline targeting. Select Criteria: Everyone to start.
- For more advanced targeting (for example, progressive rollouts), or to keep targeting criteria when you launch the experiment, reference an existing feature gate.
By default, Statsig applies no targeting criteria, and the experiment includes all allocated users within the defined layer or exposed user base.
Configure parameters and groups
Groups are the variant labels in the console, such as Control or Test. Parameters are the values your code reads to change the product or feature's behavior. Configure your parameters before your groups. For more about the difference, go to Groups vs. Parameters.
Enter the parameter values for each variant. To add a group, click the + icon next to the existing groups. Statsig adjusts the user allocation automatically as you add groups.
In the Groups section, you can also name, describe, and add variant images for each group. Group names and descriptions are labels that help you identify and compare variants in the Statsig console. Your code reads parameter values through the SDK and never reads group names, so you can rename or re-describe a group at any time without a code change or any effect on what users experience.
Device-level and custom ID experiments
By default, experiments randomize users by userID. To use a different ID type, such as stableID for device-level experiments, follow the user-level experiment steps with one change before you click Create:
- Click the ID Type dropdown menu and choose the ID type you need.
- Click Create.
Then finish configuring the experiment as you would a user-level experiment.
ID mapping capabilities
You may want to start an experiment with one ID type (such as stableID for device-level targeting) but analyze results using events from another ID type (such as userID for logged-in user metrics).
Warehouse Native: Supports ID mapping between different identifier types (for example, stableID to userID) through Entity Property Source configuration.
Cloud: Doesn't support mapping between ID types. Experiments started with stableID analyze only events with stableID, and experiments started with userID analyze only events with userID.
For advanced ID mapping requirements, consider Statsig Warehouse Native.
Isolated experiments
To create an experiment that excludes users exposed to other experiments, follow the user-level experiment steps with one change before you click Create:
- Select the Layer option, then select an existing Layer or create a new one.
- Click Create.
Then finish configuring the experiment.
Reusing experiment salts
Statsig SDKs use deterministic hashing to bucket users. Statsig buckets the same user identically for the same experiment, regardless of where evaluation occurs. Every experiment has its own bucketing salt so that each experiment's user assignment is random.
You can copy and set the bucketing salts that Statsig uses for deterministic hashing. This capability is useful for advanced use cases, such as a series of related experiments that need to reuse the control and test buckets. Only Project Administrators can copy bucketing salts. To copy a bucketing salt, click the three-dot menu button on the Experiments page.
Experiment actions menu
The three-dot (...) menu on your experiment's Overview page contains the following actions:
- Add Decision Framework: Attach a decision framework that defines success criteria and ship-versus-iterate logic for the experiment.
- Clone: Copy the experiment.
- Rename: Change the experiment's name.
- Save as Template: Save the experiment's configuration as a reusable template, which then appears as a Template option when you create a new experiment.
- Share Link: Copy a shareable link to the experiment.
- Modify Salt: Copy and set the salt used for deterministic hashing. Only Project Administrators can access this option. Refer to Reusing experiment salts.
- Export Report: Export a report of the experiment's results. This option appears after the experiment starts.
- Archive: Archive the experiment.
- Delete: Delete the experiment.
Significance level adjustments
By default, the Experiment Results section displays 95% confidence intervals without Bonferroni correction. You can change these settings during experiment setup or later in Experiment Results.
- Bonferroni Correction: Apply this correction to reduce the risk of false positives in experiments with multiple test groups. Statsig divides the significance level (α) by the number of test groups.
- Default Confidence Interval: Choose a lower confidence interval (for example, 80%) if you prefer faster results with a higher tolerance for false positives, or use 95% for greater certainty.
Target duration
A target duration is optional, but it helps you wait long enough for the experiment to reach full power. You can set the target as a number of days or a number of exposures. Use the Power Analysis Calculator to determine which target works best for your metrics.
Target durations longer than 90 days: By default, Statsig computes Experiment Results for the first 90 days, though the experiment itself can run longer. Before you set a duration beyond 90 days, consider whether results past that period are still relevant, and whether earlier data might already provide the insights you need.
After you set the target, you can track progress against the target duration or exposure count in the experiment header. Statsig also notifies you through email and Slack (if integrated) when you reach the target.
Hypothesis Advisor
Hypothesis Advisor gives instant feedback on experiment hypotheses and flags what's missing. Admins can set custom requirements that Statsig uses to guide experimenters toward more complete hypotheses.
This Statsig AI feature is off by default. Enable it from Settings > Experiment > Project > Statsig AI. On the same settings page, configure any custom requirements you want Hypothesis Advisor to enforce (for example, "Strongly recommend that a validation plan be mentioned").
Was this helpful?