For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.
Pre-Experiment Bias
How Statsig detects and corrects for pre-experiment bias caused by uneven user distributions between treatment and control groups before exposure.
Pre-experiment bias is a difference in a metric's average between the test and control groups that existed before exposure, so experiment analysis can mistake it for a treatment effect and make a result appear more or less significant than it is. Statsig runs the standard Pulse test on each scorecard metric's pre-exposure data and flags metrics where the groups already differed. Treat the flag as a caution when the metric is critical and you need an exact lift; proceed when the delta is small or CUPED absorbs it.
CUPED helps correct this bias but can't fully account for it. Some metrics, such as retention, aren't candidates for CUPED, and you can't easily adjust them.
How Statsig detects pre-experiment bias
Statsig measures the pre-experiment values of all scorecard metrics for all experiment groups by running the standard Pulse calculation on the pre-experiment period. The lookback covers one week on Statsig Cloud, and your configured CUPED lookback window on Warehouse Native. Statsig then calculates the p-value for the null hypothesis that the groups are identical, and flags results using thresholds that balance awareness against false positives from a high number of scorecard metrics or groups. When Statsig detects bias, it notifies you and places a warning on the affected Pulse results.
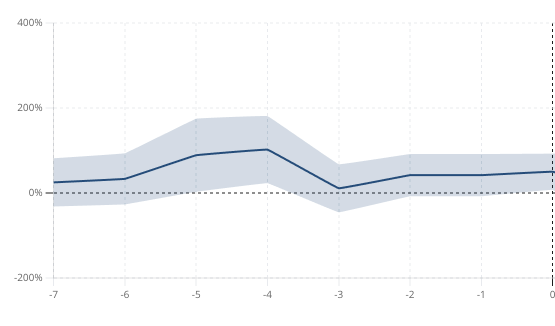
The Days Since Exposure view helps you identify novelty effects and pre-experiment effects. In the following example, the test group had a consistently higher mean than the control group in the week before exposure.
What to do when Statsig flags a metric
Pre-experiment bias can occur by chance and isn't always a problem:
- If the total delta is small, it may not meaningfully change your interpretation of results.
- If CUPED can account for the bias, the bias shouldn't affect your results.
In many cases the warning is informational, and you can proceed while treating the affected metrics with caution. Proceeding is appropriate when the metric isn't critical to the experiment, or when you care more about the direction of movement than the exact number. When the bias has no systemic source, running longer also reduces it, because new users dilute the initial imbalance.
If the metric is critical to your analysis and you need the exact value, consider resalting and restarting the experiment.
Was this helpful?