For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.
Confidence Intervals
How Statsig calculates confidence intervals for experiment metrics, including the formulas, assumptions, and how to interpret intervals in scorecards.
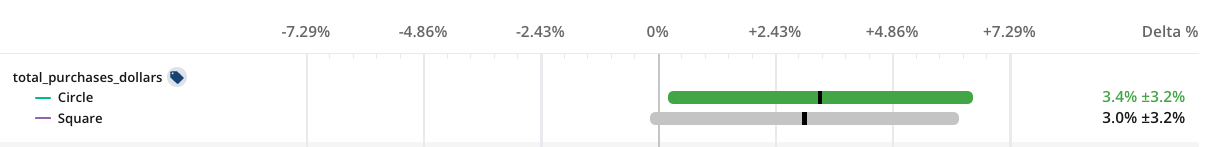
A confidence interval is the range of metric deltas consistent with your experiment data at a chosen confidence level. Statsig draws it as the gray, red, or green bar on each Pulse metric; a 95% interval that excludes zero is statistically significant at . Read the interval, not only the p-value, when you need to know how large the effect could plausibly be.
A 95% confidence interval contains the true effect 95% of the time: if you ran an experiment 100 times, the true metric delta would fall inside the interval about 95 times. If the true effect is zero, you expect the interval to exclude zero only 5% of the time (a false positive). A wider interval means less certainty about the exact size of the effect.
Computing confidence intervals
Statsig calculates confidence intervals with a two-sample z-test. The test requires the variance of the metric delta, which Statsig derives differently for each metric type; refer to standard error and mean variance. After establishing the variance of the delta, Statsig computes the confidence interval.
Two-sided tests
For the absolute metric delta, Statsig computes the confidence interval as:
where:
- is the z-critical value for the significance level you want (1.96 for the standard and 95% confidence interval) for a two-sided test.
- is the variance of the absolute delta.
The confidence interval for the relative metric delta uses one of two methods: Fieller Intervals or the Delta Method. You can choose either method. Statsig turns on Fieller Intervals by default for new customers.
With Fieller Intervals, the relative metric delta confidence interval is:
With the Delta Method, the confidence interval is:
If you use the Delta Method and the control mean isn't significantly different from zero, the interval simplifies to:
A statistically significant p-value and a relative delta confidence interval that excludes zero don't always align. The p-value of the absolute difference between test and control can be significant while uncertainty in the control mean affects the relative delta interval. With the Delta Method, the relative delta confidence interval may cross zero; with Fieller Intervals, it may appear as a point estimate.
One-sided tests
For one-sided tests, the confidence interval calculation changes to redistribute the false positive rate toward the direction you're testing, either increases or decreases in the metric:
where:
- is the z-critical value for the significance level you want (1.645 for the standard and 95% confidence interval) for a one-sided test.
- is the variance of the absolute delta.
- The interval Statsig uses depends on whether the one-sided test looks for increases or decreases in the metric.
Welch's t-test for small sample sizes
For small sample sizes, Statsig uses Welch's t-test instead of a z-test. Welch's t-test handles samples of unequal size or variance without increasing the false positive rate. The confidence interval has the same form as the two-sample z-test interval for one- and two-sided tests, with the t-critical value with degrees of freedom in place of the z-critical value.
For a two-sided test, the confidence interval is:
where and are the number of users in the test and control groups. For a large number of degrees of freedom, the t-statistic converges with the z-statistic, so Statsig uses Welch's t-test only when .
Comparing experiment data to a fixed baseline with a one-sample t-test
To answer a question such as "Does my test variant lead to a click-through rate higher than 0.5?", define a fixed-baseline comparison when you add metrics to the experiment. For details, refer to one-sample tests.
Statsig calculates the confidence interval as:
Was this helpful?