Power Analysis
Learn how to use Statsig's Power Analysis Calculator to determine experiment parameters needed for statistically significant results.
The Power Analysis Calculator is Statsig’s experiment-sizing tool. It uses historical traffic and metric statistics from a population you choose (such as everyone, a targeting gate, a qualifying event, a metric source, or a previous experiment) to estimate the relationship between your planning variables.
The Experiment Setup panel recalculates those results against your planned group count, split, significance level, statistical power, CUPED, and multiple-comparison correction without re-running the analysis. You can run it before you create the experiment. Its output is the target duration you enter during setup. You can save the report or attach it to the experiment so the sizing decision stays with the test.
After you launch an experiment, use the Power Analysis Calculator to read the confidence intervals on the experiment's Results tab. For more information on experiment results, go to How to read experiment results.
Variables the calculator estimates
The calculator uses historical metric statistics and traffic volume to estimate the relationship between three variables:
- Minimum detectable effect (MDE): The smallest change in the metric that the experiment can reliably detect. For example, at 80% statistical power, an effect equal to the MDE has an 80% chance of producing a statistically significant result. For a metric with a mean of 10 page loads per user, a 10% MDE corresponds to one page load per user.
- Duration and exposures: How long the experiment runs and how many users enter its groups. Longer experiments typically have more observations, which can reduce the detectable MDE. Statsig uses historical traffic to estimate exposures by week.
- Allocation: The percentage of eligible traffic assigned to the experiment. Increasing allocation generally increases group exposures and reduces the detectable MDE for a given week. Set the planned allocation in Experiment Setup to compare durations and detectable effects.
Run a power analysis
- To run a power analysis, first go to Experimentation > Power Analysis.
- On the Calculator tab, under Population, choose users who resemble those you plan to include in the experiment:
- Everyone: When available, analysis uses the users for the selected ID Type, for example User ID.
- Targeting Gate: Use users who pass a gate that matches your planned targeting.
- Qualifying Event: Use users who logged a relevant event. Add filters if needed.
- Previous Experiment: Use a prior experiment with a similar audience.
- Under Metrics, search for and select one or more metrics to analyze.
- Click Run Power Analysis.
The analysis runs in the background and can take some time. Statsig notifies you through email when the analysis is ready. You can leave the page or click Start a new analysis while it runs.
Find and attach past analyses
Go to Experimentation > Power Analysis > Past Analyses to view previous power analyses.
You can attach a previous analyses to your experiment. Attaching an analysis links the sizing decision to the experiment it justifies. The MDE, allocation, power, and duration that you planned for remain visible on the experiment. Attaching analyses to experiments keeps information highlighted and visible. The link works in both directions and is recorded in the experiment’s change log, which gives reviewers and teammates an auditable answer to “why is this experiment running for six weeks?”. It also lets you compare the observed effect against the MDE you sized for rather than rebuilding the estimate from scratch.
To attach an analysis to an experiment, do either of the following:
- On the Past Analyses tab, click the ⋯ menu on the analysis and select Attach to Experiment.
- In an open analysis, click Attach Experiment.
Population types
The selected population determines the historical traffic and metric statistics used in the estimate. A population that doesn’t match the users your experiment reaches may give misleading results, whether it’s broader or narrower than the planned audience. The following examples describe how populations can affect results:
Example: checkout flow with the Everyone population
You want to test a change in the checkout flow and estimate the MDE for total_purchases. If only about 10% of your daily users reach the checkout page and you use the Everyone population, the analysis is likely to:
- Overestimate the number of users the experiment gets.
- Underestimate the mean value of the
total_purchasesmetric if users who do not reach checkout rarely purchase. Those users are included in the historical average but would not enter the planned experiment. - Incorrectly estimate the variance of the
total_purchasesmetric because users outside the checkout flow may behave differently.
For a checkout experiment, a previous experiment that reached checkout users can provide more representative traffic and metric data.
Example: onboarding flow with a previous experiment population
You want to test a new onboarding flow for everyone who signs up. he only prior experiment available ran on iOS users in a single country. If you use that experiment as the population, the analysis is likely to:
Underestimate the number of users the experiment gets, because the prior experiment reached a fraction of your signups. The estimated duration is then longer than the experiment needs. Describe the metric for iOS users in one country. If those users convert differently than the rest of your signups, the MDE estimate doesn’t reflect the planned audience. An estimate that’s too pessimistic can lead you to shelve an experiment that your traffic supports. When no prior experiment matches the audience you plan to reach, use a targeting gate or qualifying event that reproduces the condition users meet to enter the experiment.
Read the results
To open your analysis (if it isn't attached to an experimnet), go to Experimentation > Power Analysis > Past Analyses and select the analysis you want.
A completed analysis is arranged to display both the inputs that it used as well as the results. In the results, choose the metric you want summarized in Target Metric. The results tabs update to answer different target metric questions.
The following sections describe different types of information and analyses provided by the power analysis calculator:
Week by Week breakdown
If you know the available allocation, the Week by Week breakdown tab displays the detectable MDE for each metric over time. Select a week to see its estimated control and test exposures. You can enter a target MDE to highlight weeks that meet your goal. The target is a planning threshold, not a predicted effect.
As cumulative exposures grow, the detectable MDE often decreases. Each week's estimate also uses that week's metric statistics. This meanss that the MDE need not decrease every week.
Scenario Matrix
If you know the effect size you want to detect, the Scenario Matrix tab estimates the weeks needed for different group sizes and target MDEs. Select a cell to see the estimated control and test exposures. You can add a custom group size or MDE. Estimates beyond observed history use projected traffic, so treat them as planning estimates.
Experiment Setup options
Use the Experiment Setup section to match the analysis to your planned experiment. Changes recalculate the displayed results from the saved historical analysis. Click Save Changes to keep your settings and result selections. To recompute with different populations or metrics, make the edits you want and then click Re-Run Analysis.
- Number of Groups: The total number of groups in the experiment, including control.
- Group Split: Choose an equal split or set a different control group percentage.
- Allocation (% of eligible traffic): The percentage of eligible traffic available to the experiment.
- Significance Level (α): The significance level for the test, entered as a percentage. Typically 5%.
- Statistical Power (1-β): The statistical power for the test, entered as a percentage. Typically 80%.
- CUPED: Apply CUPED variance reduction when available for the selected analysis.
- Stats Method: Two sided test or One sided test.
- Apply Bonferroni Correction Per Variant: Whether to include α correction for multiple tests in the power analysis.
Expand Advanced Statistics to inspect the historical metric statistics used in the estimate.
Calculation details
Statsig estimates MDE from the historical metric mean and variance and the expected exposures in each group. The estimate also reflects the power, significance level, test method, and multiple comparison correction selected in Experiment Setup. This formula shows a two-sided test with no Bonferroni correction and a positive metric mean. For other settings, Statsig adjusts the statistical threshold and uses the absolute value of the mean.
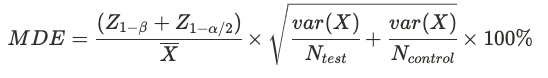
where:
- and are the normal quantiles for the statistical power and significance level set in Experiment Setup.
- is the historical mean of the metric for the selected population.
- is the historical variance of the metric for the selected population.
- and are the expected exposures in the test and control groups.
Was this helpful?
For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.