For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.
Fieller Intervals
How Statsig uses Fieller intervals to construct confidence intervals for ratio metrics in experiment analysis, with formulas and interpretation notes.
Fieller intervals give an exact confidence interval for the relative change between test and control groups, accounting for the uncertainty in the control mean that forms the denominator. Statsig recommends Fieller intervals over the delta method, which approximates the variance of the ratio and builds a confidence interval from that approximation. Fieller intervals stay reliable when sample sizes are small or denominators are noisy; the two methods agree in most other cases.
How Statsig calculates a Fieller interval
Check that the Fieller interval is well defined
Before applying Fieller's theorem, Statsig checks that the denominator of the relative lift metric, , is significantly distinct from 0.
Statsig calculates the parameter :
Where:
- is the critical value for the confidence level you select.
- is the variance of the control group metric values.
- is the number of units in the control group.
- is the mean of the control group metric values.
When is less than 1, the control mean is significantly different from 0, and Statsig uses the Fieller interval.
Apply the Fieller interval formula
Because the control and test group results are independent of each other, Statsig drops the covariance terms in Fieller's theorem.
Where:
- is the mean of the test group metric values.
- is the variance of the test group metric values.
- is the number of units in the test group.
Handle a control mean that isn't distinct from zero
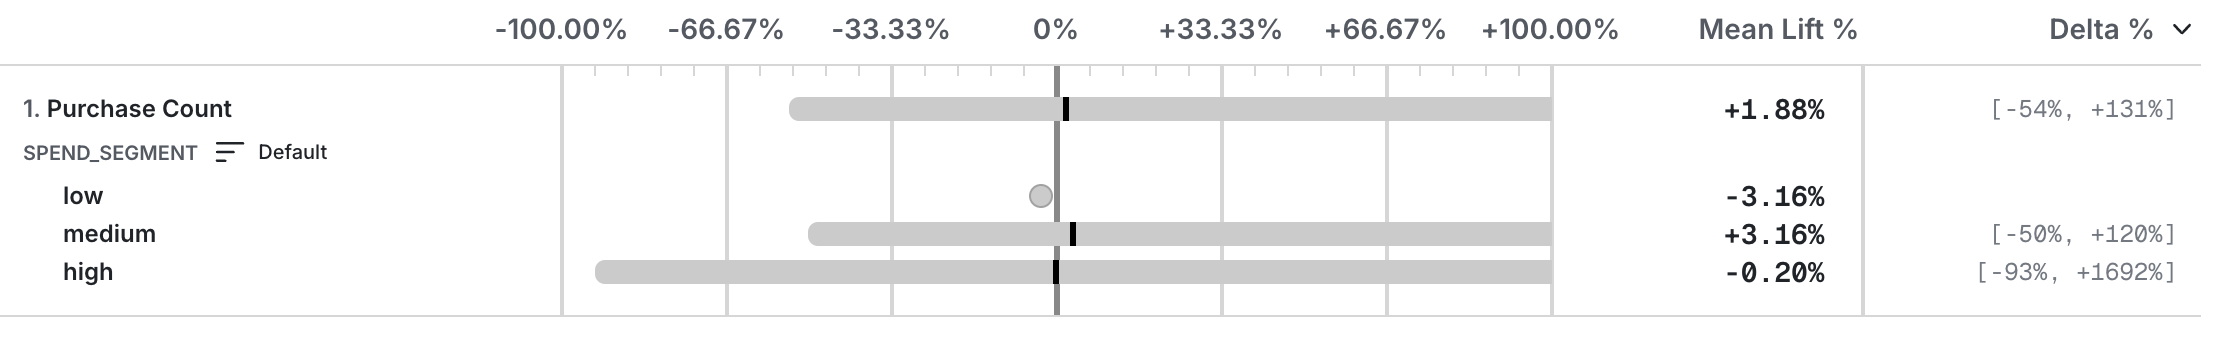
In rare cases (less than 5% of observed metric comparisons on Statsig), is greater than or equal to 1, which means the control group's mean isn't statistically distinguishable from 0.
When isn't statistically different from zero, the denominator of the relative lift calculation is unstable, so the confidence interval for the percent difference between test and control is unbounded.
When the confidence interval is unbounded, Statsig surfaces the relative lift observed during the experiment:
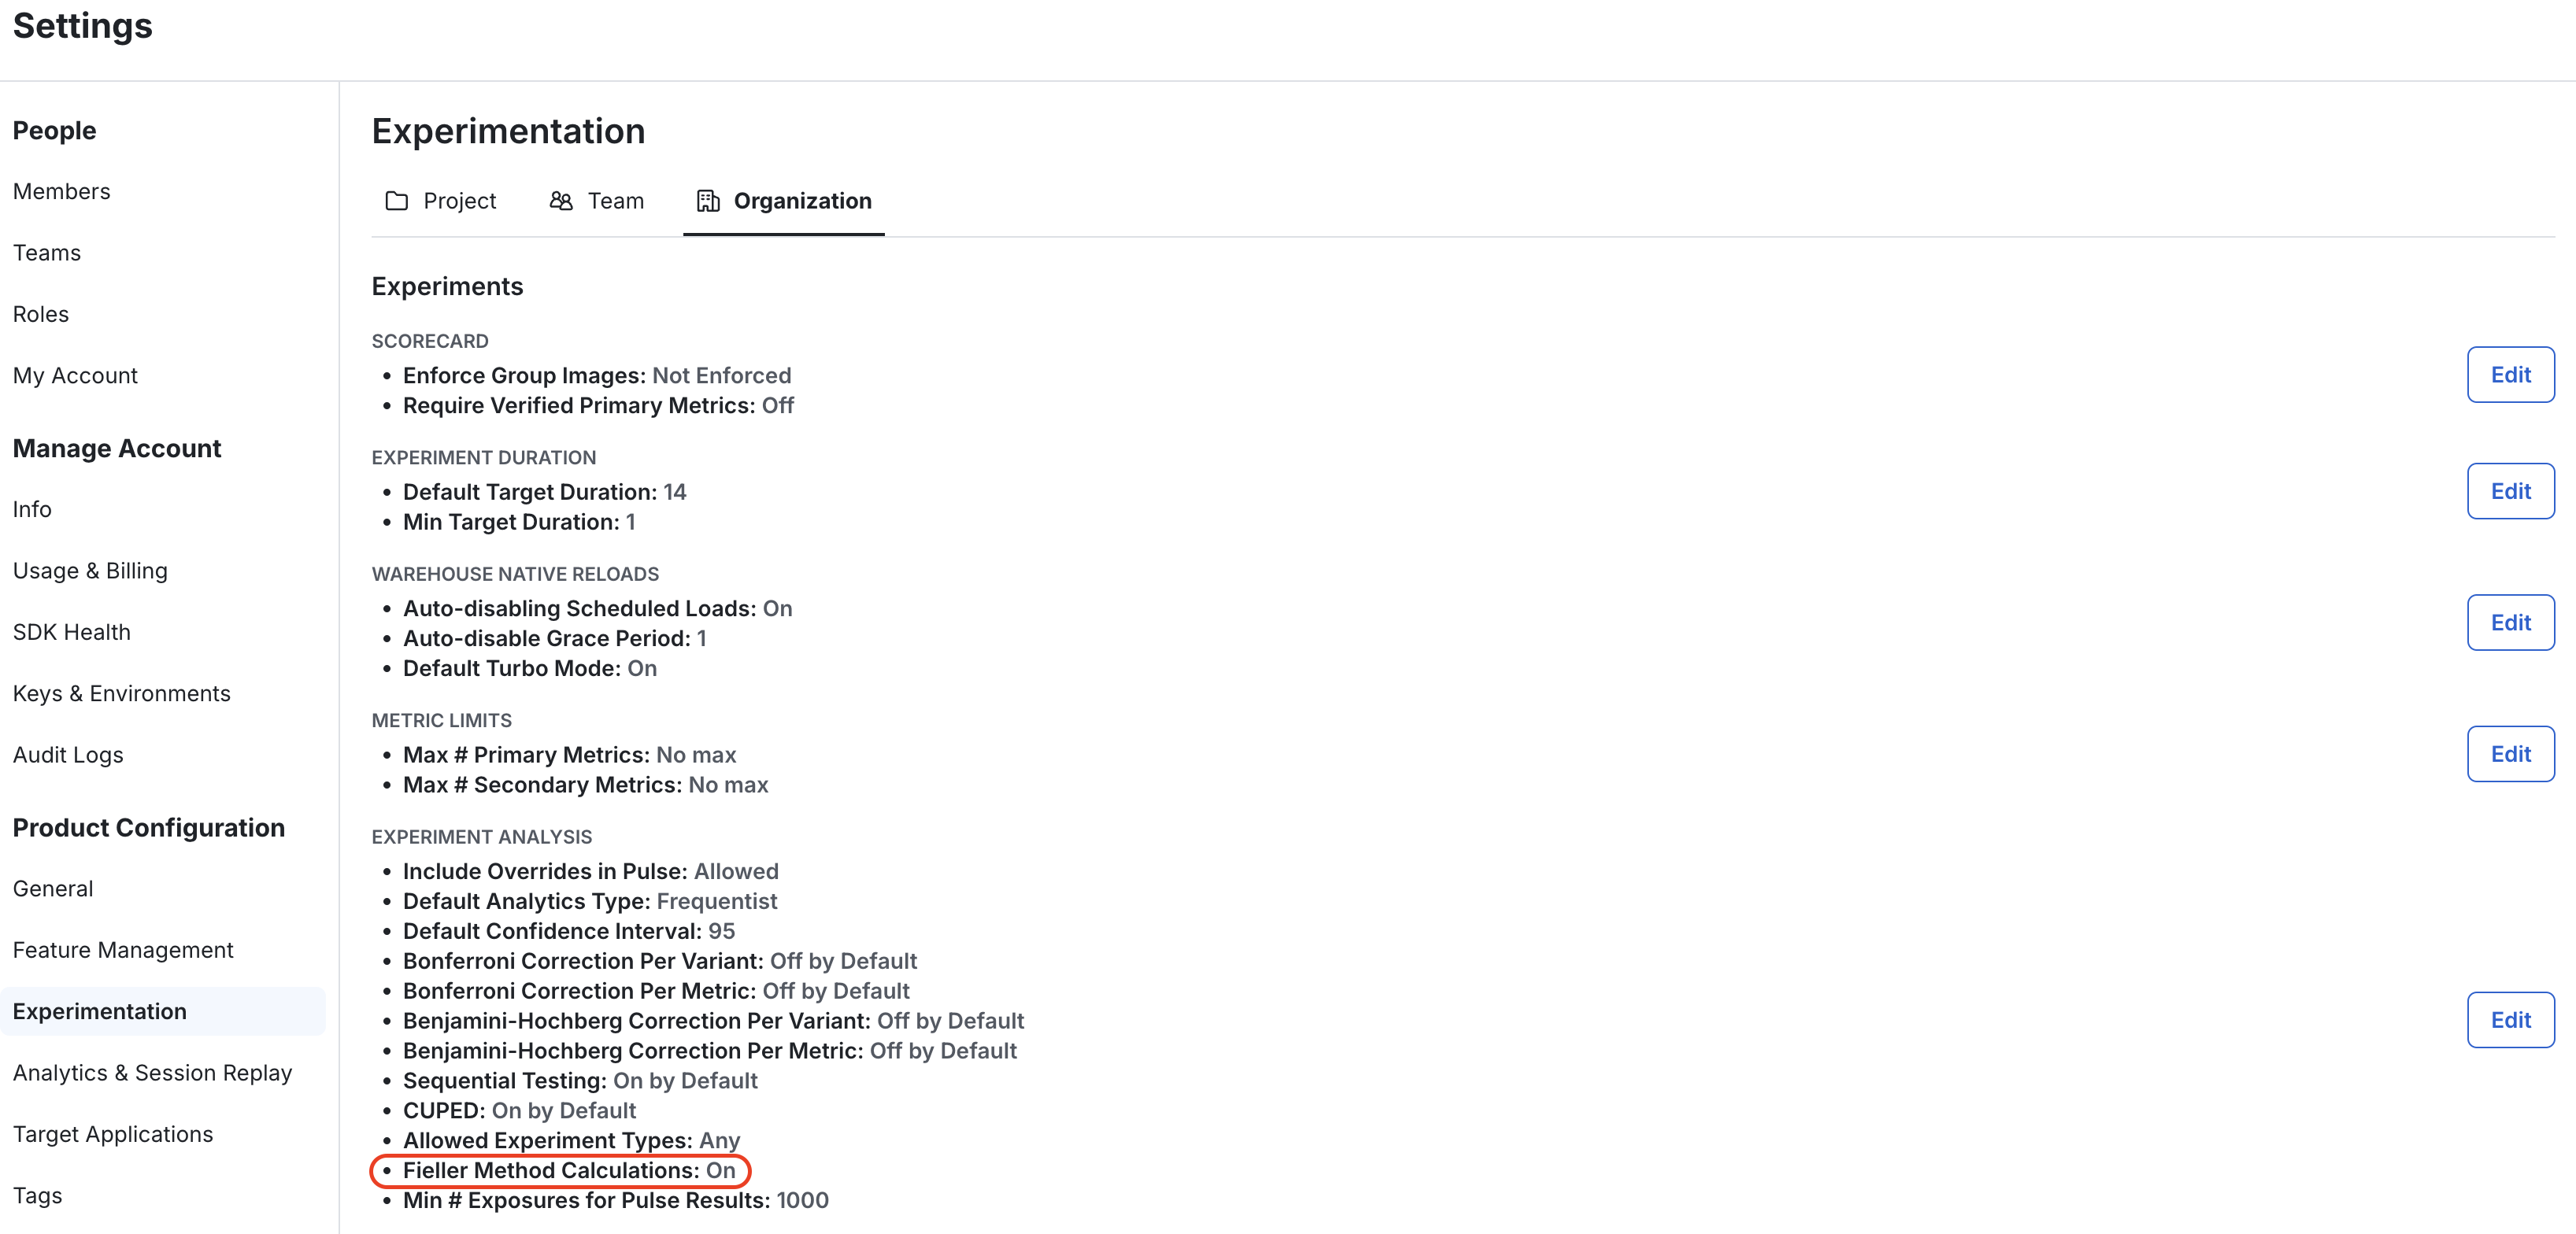
Enable Fieller intervals in Statsig
Configure the relative confidence interval methodology in your Experimentation Settings at the organization level. Changing this setting affects only experiments created after the change.
In the experiment scorecard, Fieller intervals appear as shown:
Was this helpful?