For AI agents: a documentation index is available at /llms.txt. Append .md to any page URL for markdown, or send Accept: text/markdown.
Experiments Overview
Learn the fundamentals of experimentation with Statsig, including key concepts, randomization units, and statistical significance.
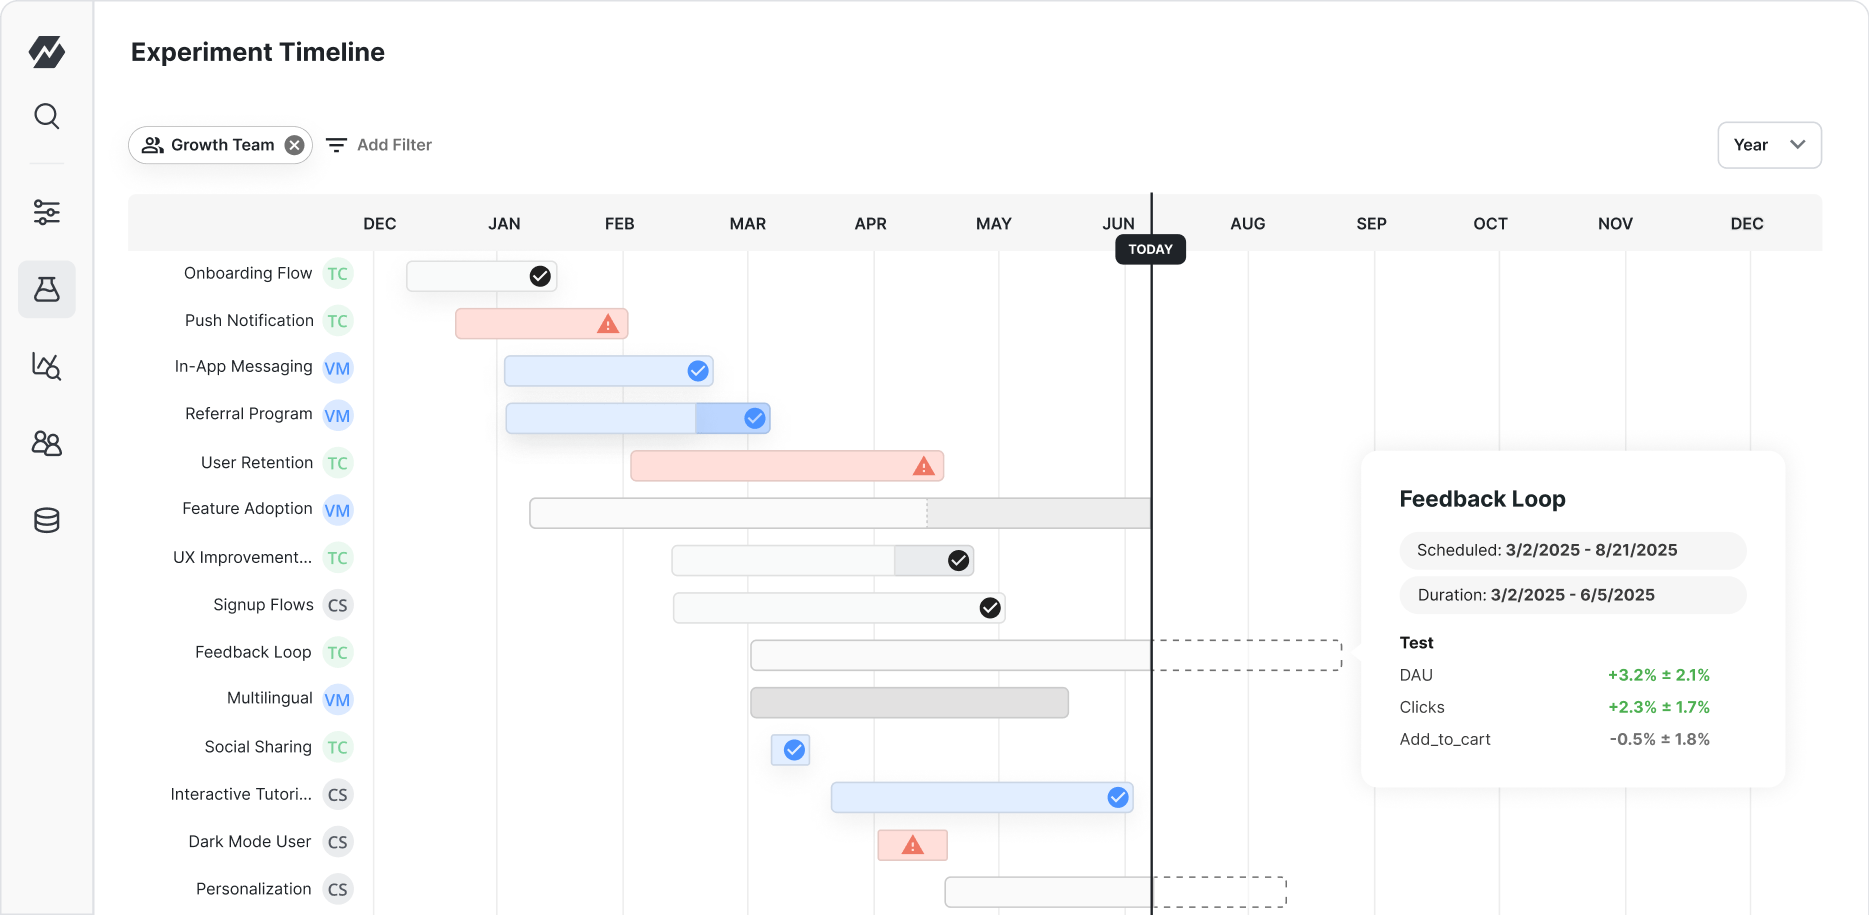
An experiment in Statsig is a randomized controlled trial (an A/B or A/B/n test). Statsig splits users into a control group and one or more test groups, serves each group a different variant, and reports metric lifts with confidence intervals. Use an experiment when you need to know whether a change caused a metric to move. To roll out a change without measuring variant lift, use a feature gate instead.
Key concepts
Every experiment you run on Statsig builds on the following concepts:
Control variables
A control variable is the variable in an experiment that you manipulate to observe its effect on key metrics. In a simple A/B test, the control variable has two values (A and B). The A variable doesn't change. It is the variable against which you evaluate your results. The B variable is a single change you want to evaluate. In A/B testing, you don't want to introduce more than one change in an experiment. More complex experiments have more values (for example, A, B, C, and D). Experiments with more than two values are also known as multivariate experiments.
Variants
A variant is a specific version of the product or feature you're testing. For example, in an A/B test:
- A (Control): The current state of the product or feature.
- B (Test): The modified state you want to evaluate. This is the change you're testing.
Statsig randomly assigns users to each variant. This lets you compare variant performance across equally represented groups.
Statistical significance
Statistical significance determines whether the observed changes in metrics are likely due to the product change or to random variation. Statsig reports two measures:
- p-value: The probability of observing the results by chance if the variant had no effect. A p-value below 0.05 typically indicates statistical significance.
- Confidence interval: The range in which the true effect of a variant lies, with a given level of confidence. If the confidence interval (for example 95%) doesn't overlap zero, the effect is statistically significant.
For more information on designing, monitoring, and analyzing experiments, go to Product Experimentation Best Practices.
Randomization unit
The randomization unit is the entity, such as a user, a device, or a session, that Statsig randomly assigns to the control group or a test group. Every value of that unit always receives the same variant. The unit is also the basis of measurement for your metrics. You set which entity you want to use for the randomization unit. For example, if you set userID as the randomization unit, Statsig buckets each user by userID as well as your analysis reports metrics such as revenue per userID.
You can select one of the following randomization units:
User identifiers
Your application generates a user ID when a user registers or signs in. Use userID as the randomization unit for experiments on logged-in experiences. For more details on user identifiers, go to User Identifiers.
Device identifiers
Statsig generates a stableID, a device identifier unique to Statsig, for each device that interacts with your product. For example, when a guest opens your product on an iOS device, Statsig creates a stableID for that device and tracks the device's actions through it. Use stableID as the randomization unit for experiments on unregistered or guest users, such as landing page changes aimed at improving registration rates. For more details, go to Statsig Guide for Device-Level Experiments.
Session identifiers
Use a session ID as the randomization unit when you test behavior within a single session, such as a guest checkout flow that users typically complete in one visit. Session-based randomization assumes each session is independent of every other session.
For best results, choose the randomization unit that matches where users are in your product at the moment when the assignment happens. A mismatch causes unintentional crossovers between groups and skews your results. The following table compares the common randomization units:
| Unit | Advantages | Drawbacks |
|---|---|---|
userID | Persistent across sessions and devices. Statsig assigns the same variant wherever and whenever the user signs in. Doesn't rely on client-side cookies, which users can clear. | Unavailable before sign-in. This means it doesn't fit flows such as landing pages or account creation. Misses pre-login behavior because assignment starts at sign-in. |
stableID (device) | Reaches anonymous and first-time visitors who don't have a userID. Serves the same variant on a device whether or not the user signs in. Connects logged-out and logged-in activity on that device. | Different devices for the same user may receive different variants. Shared devices treat several users as one. Not suited to long-term studies: clearing cookies or switching devices creates a new stableID that isn't linked to the previous one. |
Session ID | Scopes the experiment to one visit, so you can measure a self-contained flow without cross-session carryover. Doesn't require a persistent identity. Exposures accumulate quickly, which can shorten the time to statistical power. | Users may remember their experience from one session to another, which breaks the session-independence assumption. Returning users may land in different variants. |
Was this helpful?